System Design Interview : Multi-version Concurrency Control in Databases — The icebreaker for deciding which relational database to choose
Multi version concurrency control plays an important role in deciding relational databases. Each database management system choses different approaches in implementing it with their own pros and cons. Understanding it in depth helps in taking better tradeoffs when taking the decision.
A software engineer, currently working at licious. Loves solving problems using software engineering.
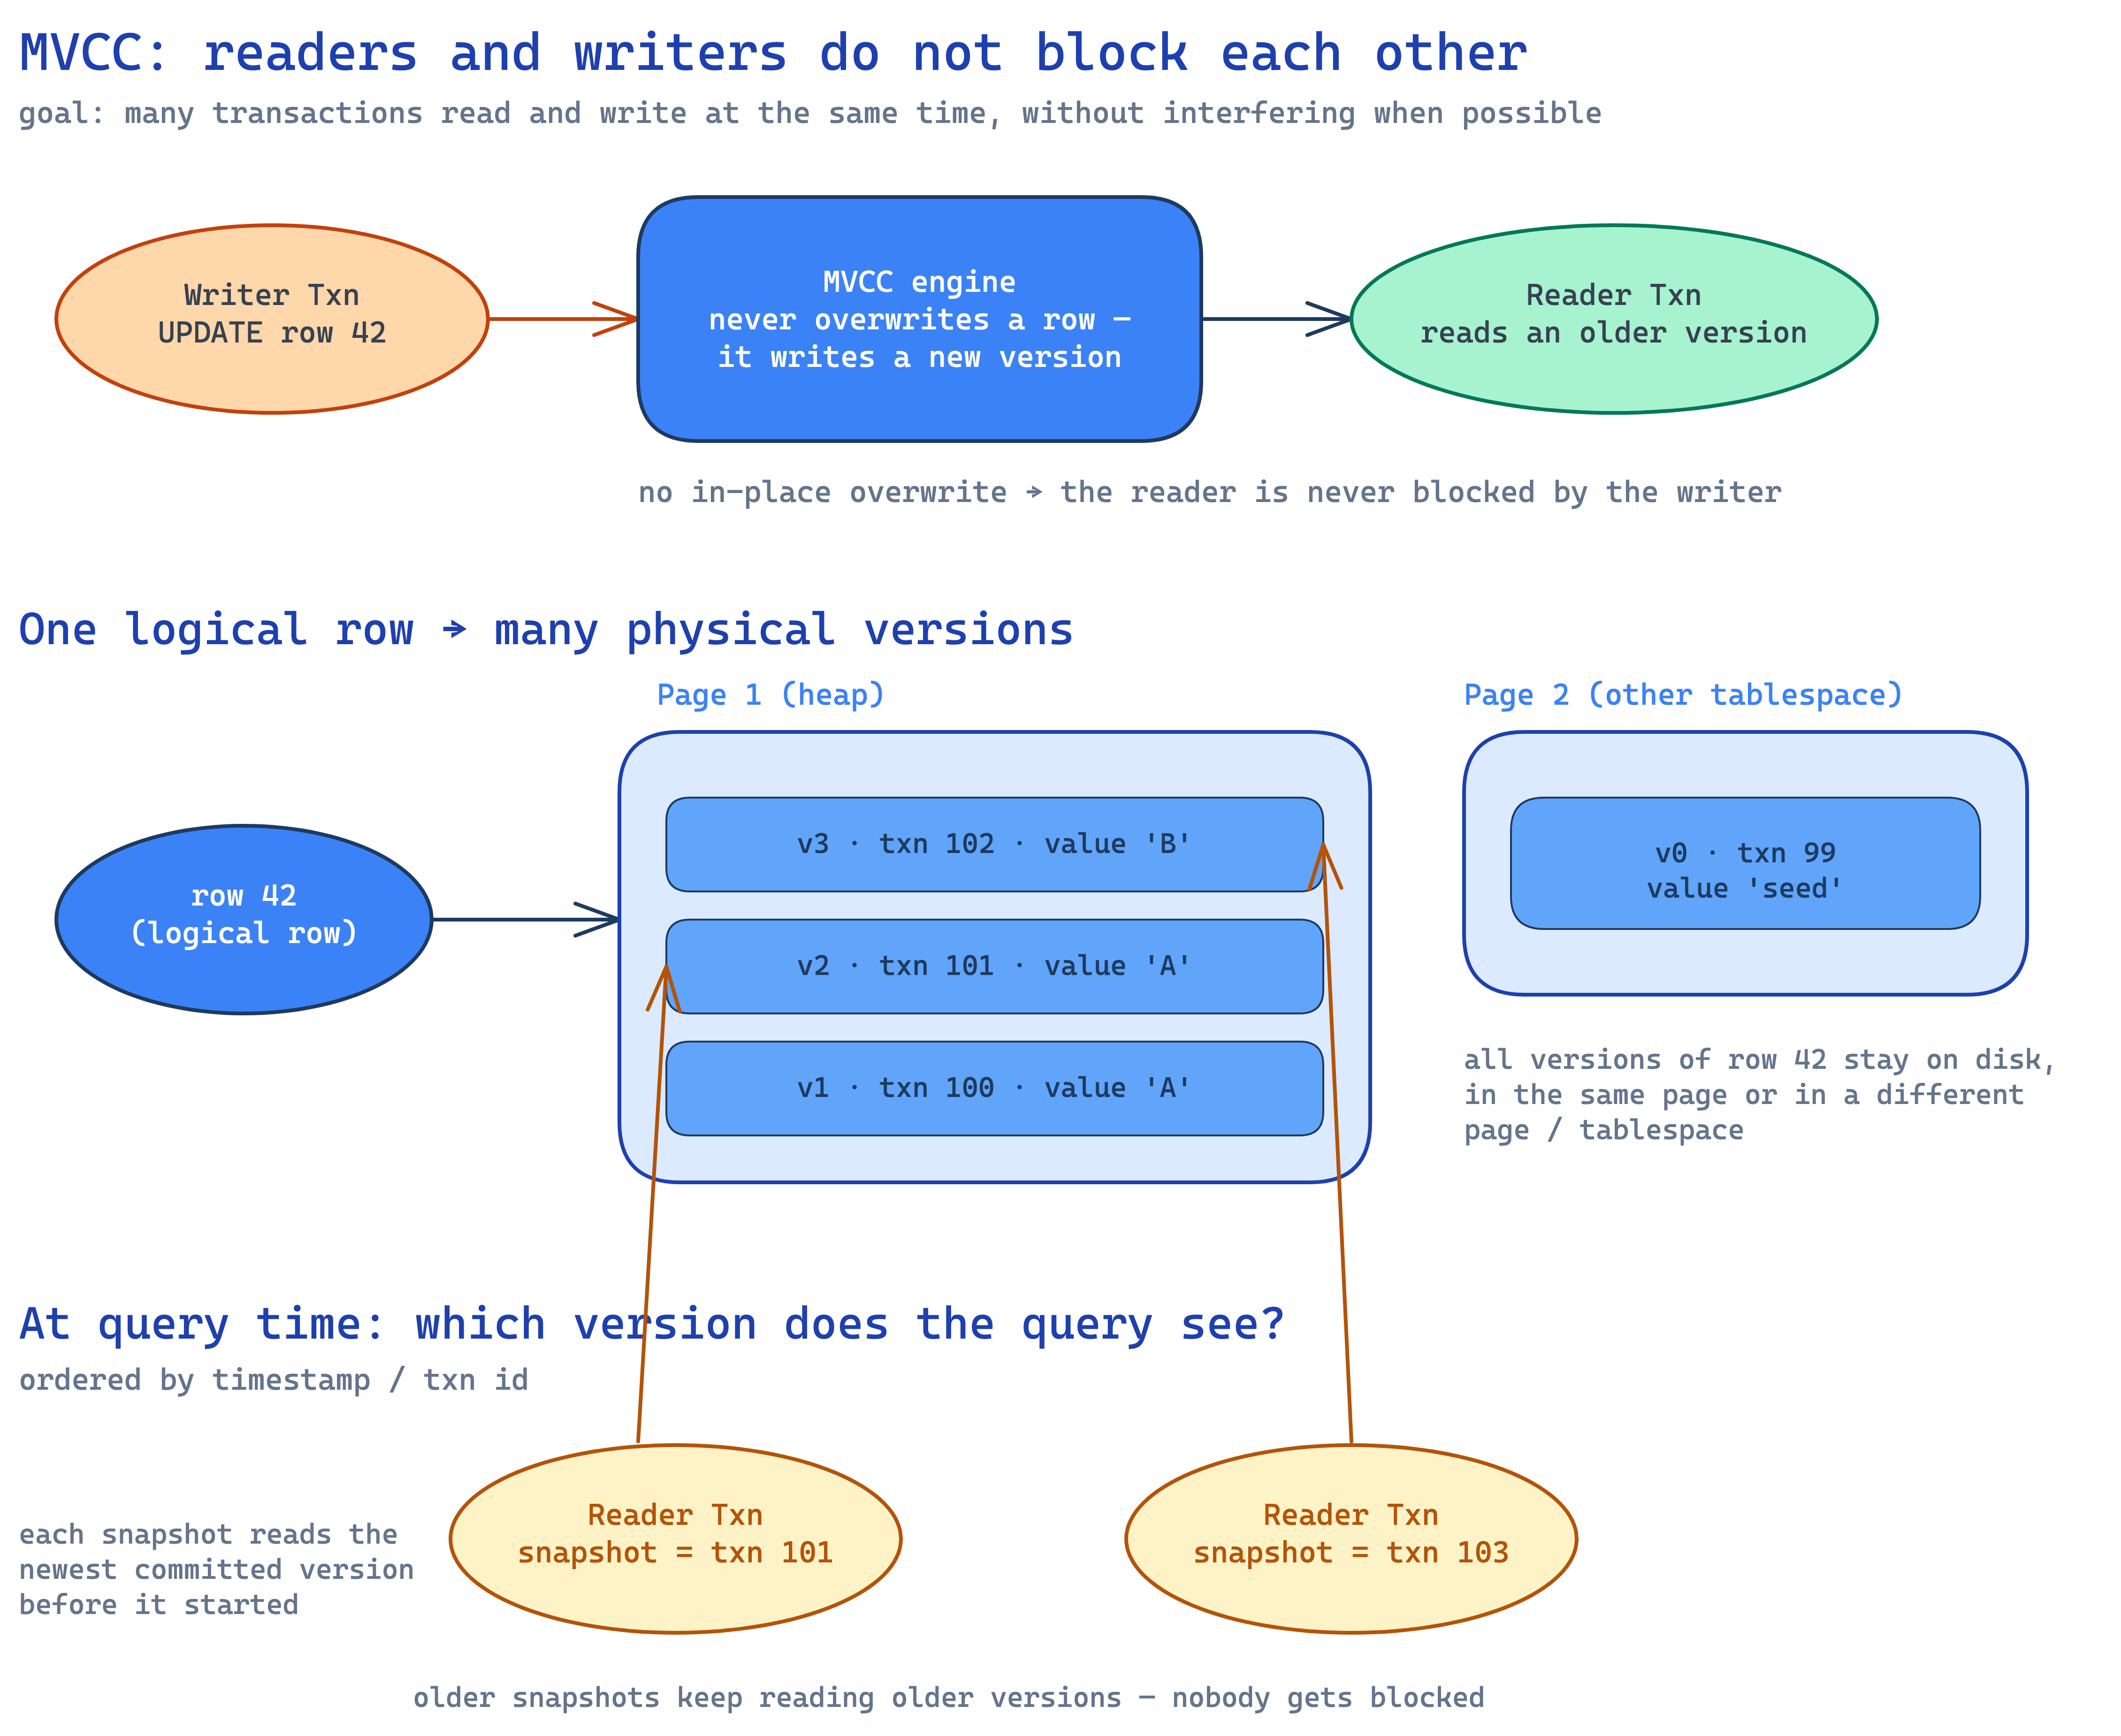
The goal of MVCC in a DBMS is to allow multiple transactions to read and write to the database simultaneously without interfering with each other when possible.
The basic idea of MVCC is that the DBMS never overwrites existing rows. Instead, for each (logical) row, the DBMS maintains multiple (physical) versions in the same or different disk pages.
When the application executes a query, the DBMS determines which version to retrieve to satisfy the request according to some version ordering (timestamp, transaction ids etc...). The benefit of this approach is that multiple queries can read older versions of rows (snapshot) without getting blocked by another query updating it.
MVCC boils down to these questions
How to store updates to the existing rows?
How to find the correct version of a row for a query at runtime?
Whether to update indexes to point to multiple versions or point to clustered index and fetch the versions from there?
How to remove expired versions that are no longer visible?
PostgreSQL
PostgreSQL follows the append-only method of copying the same row, applies the updates to the copied row, stores in the same tablespace, updates it's version and updates the version chain. The database engine forms a singly-linked list for the version chain.
Copying of the whole row whenever one column updates adds massive data duplication and increases storage. Whereas MySQL and Oracle stores a compact delta between the two rows instead of copying the whole tuple.
At the query time, the database engine traverse through the version chain and finds the latest version.
Old row versions also pollute the buffer cache. A sequential scan reads every page of a table, including pages that hold mostly old versions. Each such page can evict a useful page from the cache, so the cache fills with pages that carry little live data.
PostgreSQL has a protection mechanism for this. Sequential scans use a buffer access strategy with a small ring of buffers (256 kB by default) and reuse only those buffers. A large scan therefore cannot flush the working set out of the cache.
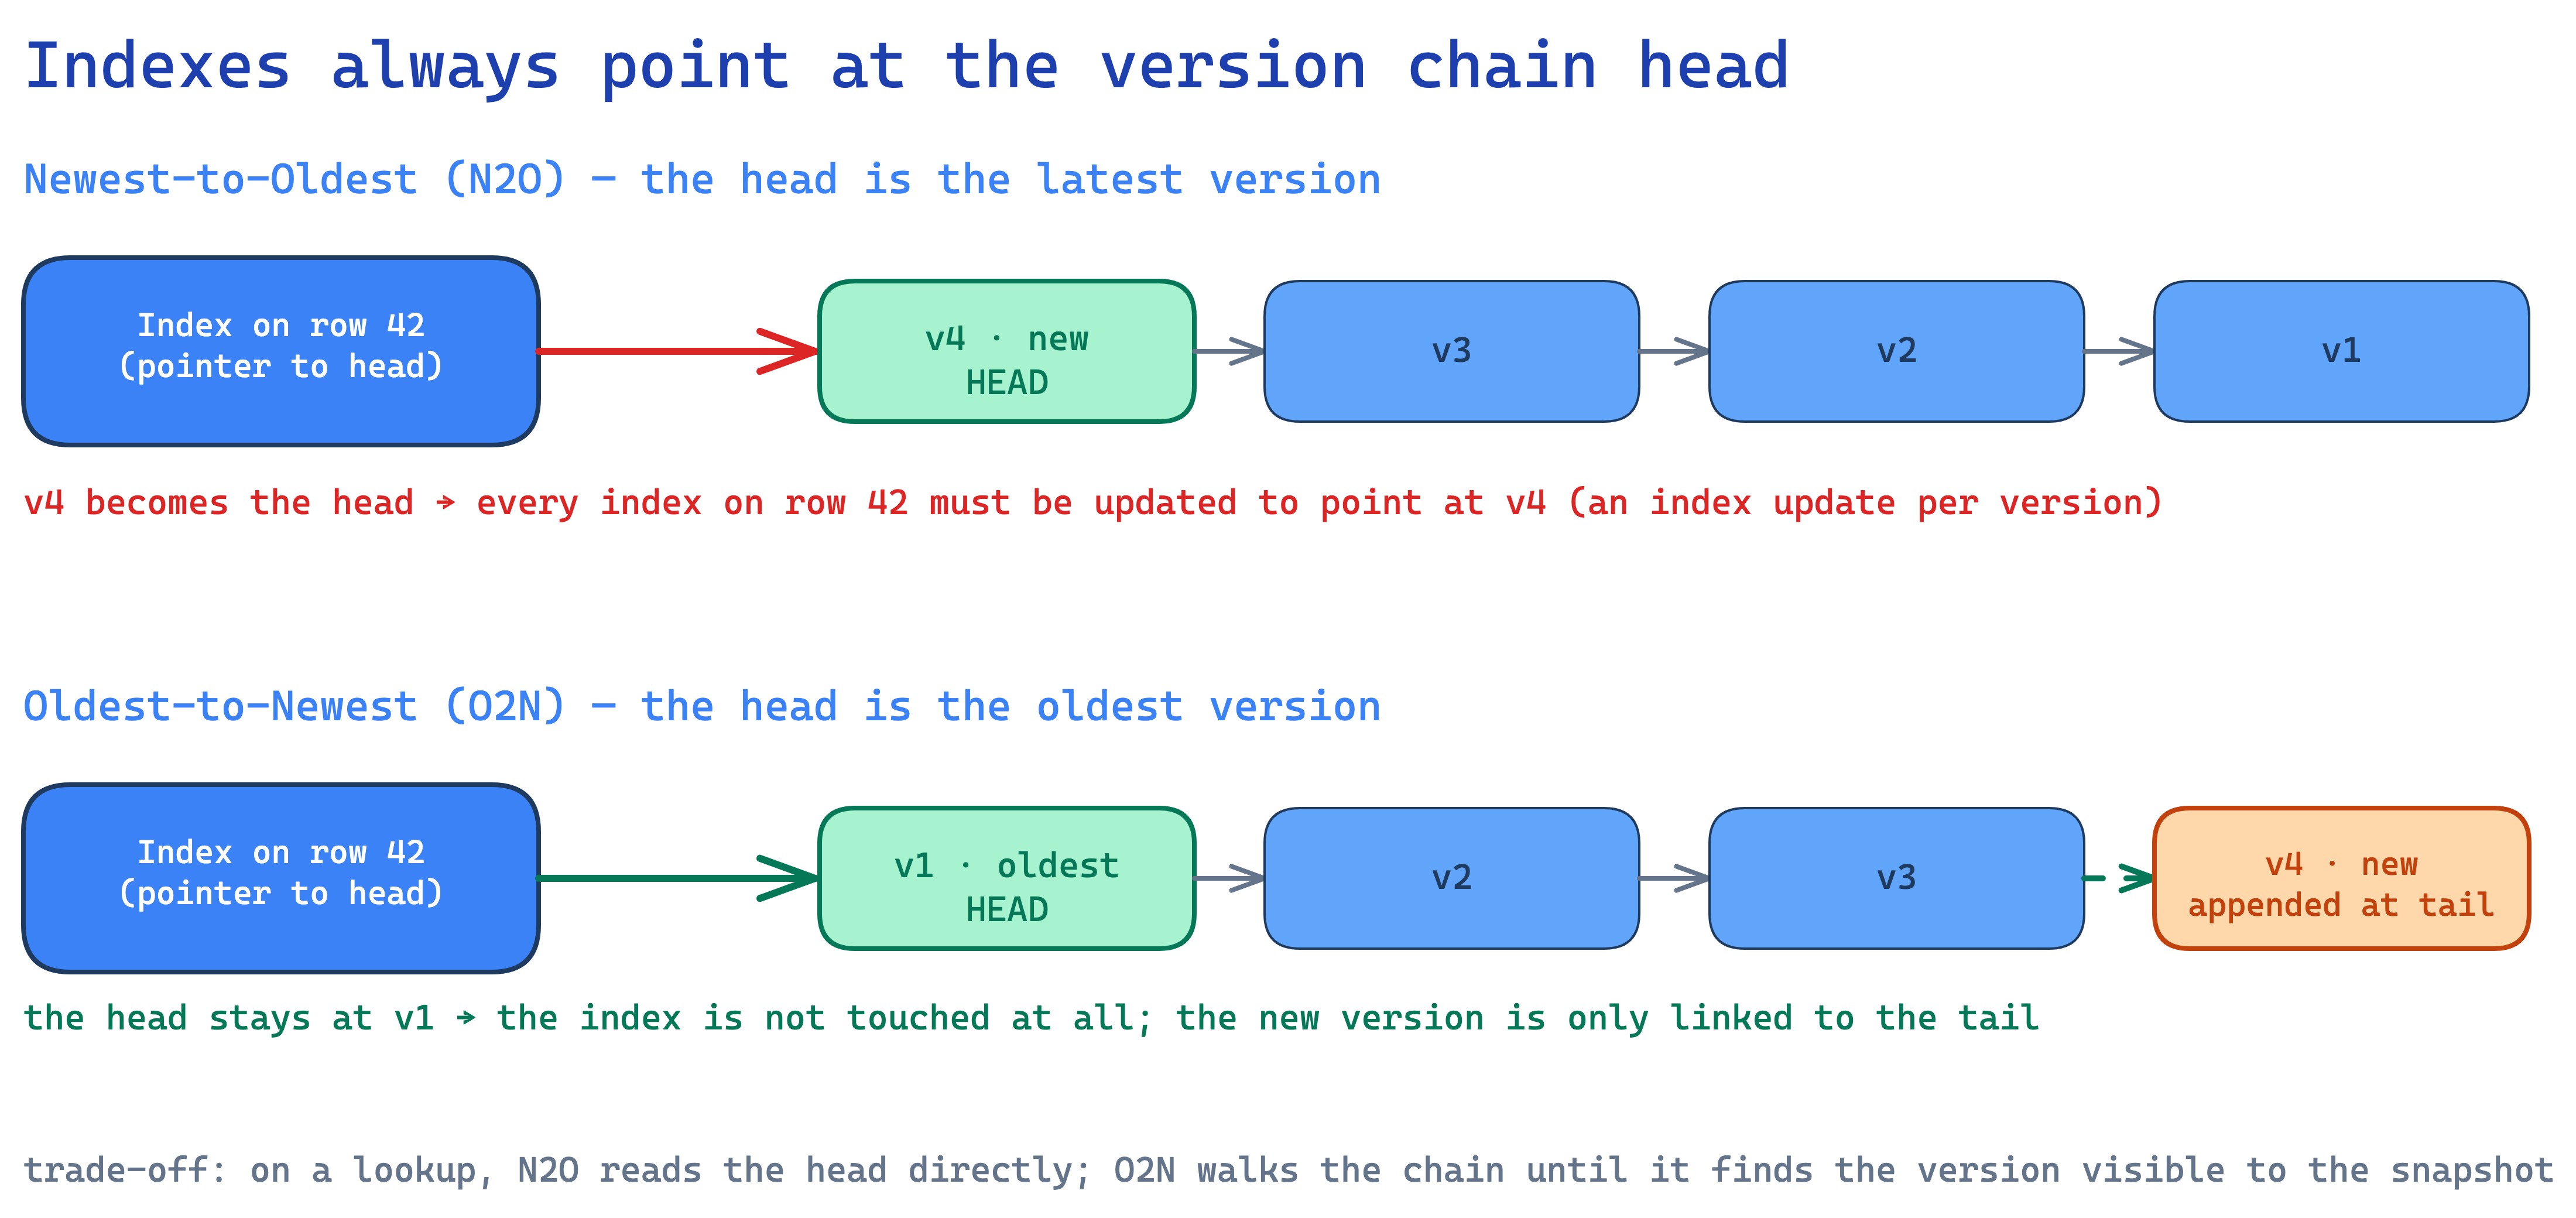
There are two ways a version chain can be stored. Newest-to-oldest (N2O) or oldest-to-newest (O2N).
New-to-old (N2O) vs old-to-new (O2N)
Indexes always point to the head of the version chain. The head is the latest version in N2O, and the oldest version in O2N.
| New-to-Old (N2O) | Old-to-New (O2N) | |
|---|---|---|
| Pointer direction | each version points to its previous version | each version points to its new version |
| Chain head | the latest version | the oldest version |
| Index | points at the head, so a new version moves the head → every index on that row must be updated | points at the head, which never changes → no index update on a new version |
| Where the new version goes | becomes the new head | appended at the tail |
| Lookup | head already holds the newest version, no traversal | walk the chain to find the version visible to the snapshot |
| Used by | most DBMSs, including Oracle and MySQL | PostgreSQL |
The O2N trade-off is the lookup cost: the DBMS may walk a long version chain before it finds the version that the snapshot may see. N2O reads the head directly, but pays an index update on every version.
PostgreSQL - Heap-Only Tuple Optimisation
PostgreSQL stores the next version pointer in
t_ctidfield in the row header. When a row is updated, PostgreSQL updates this field to the next version.During the reads, to avoid traversing the entire version chain, PostgreSQL adds an entry to the leaf nodes of table’s all indexes for each physical version of a row. But, during the write/updates, the DBMS incurs additional I/O to traverse each index and insert the new entries. Accessing an index introduces lock contention in both the index and the DBMS’s internal data structures such as buffer pool cache.
Imagine having 50 columns and 10 indexes in a table, updating a row creates a new versioned row in the same tablespace, goes to all 10 indexes and creates a new leaf node that point to the new version.
Oracle and MySQL do not have this problem in their MVCC implementation because their secondary indexes do not store the physical addresses of the new versions. Instead, they store a logical identifier that the DBMS then uses to look up the current version’s physical address. But, this will make secondary index reads slower as the DBMS has to resolve the logical identifier to the physical address through the primary key index.
MySQL’s InnoDB appends the primary key columns to each secondary index record and uses that value to search the row in the clustered (primary key) index.
Oracle stores the primary key as a logical ROWID in its secondary indexes.
The flow appears as below. From the clustered index, the DBMS obtains the physical address, then it checks the version metadata (InnoDB's DB_TRX_ID, Oracle's SCN/ORA_ROWSCN) against the reader's transaction snapshot version. If the current version isn't visible, the DBMS reconstructs the older version from the undo log / rollback segment .
secondary index → PK → clustered index → current physical address
                                        ↓
                    check txn id vs snapshot → reconstruct old version from undo if needed
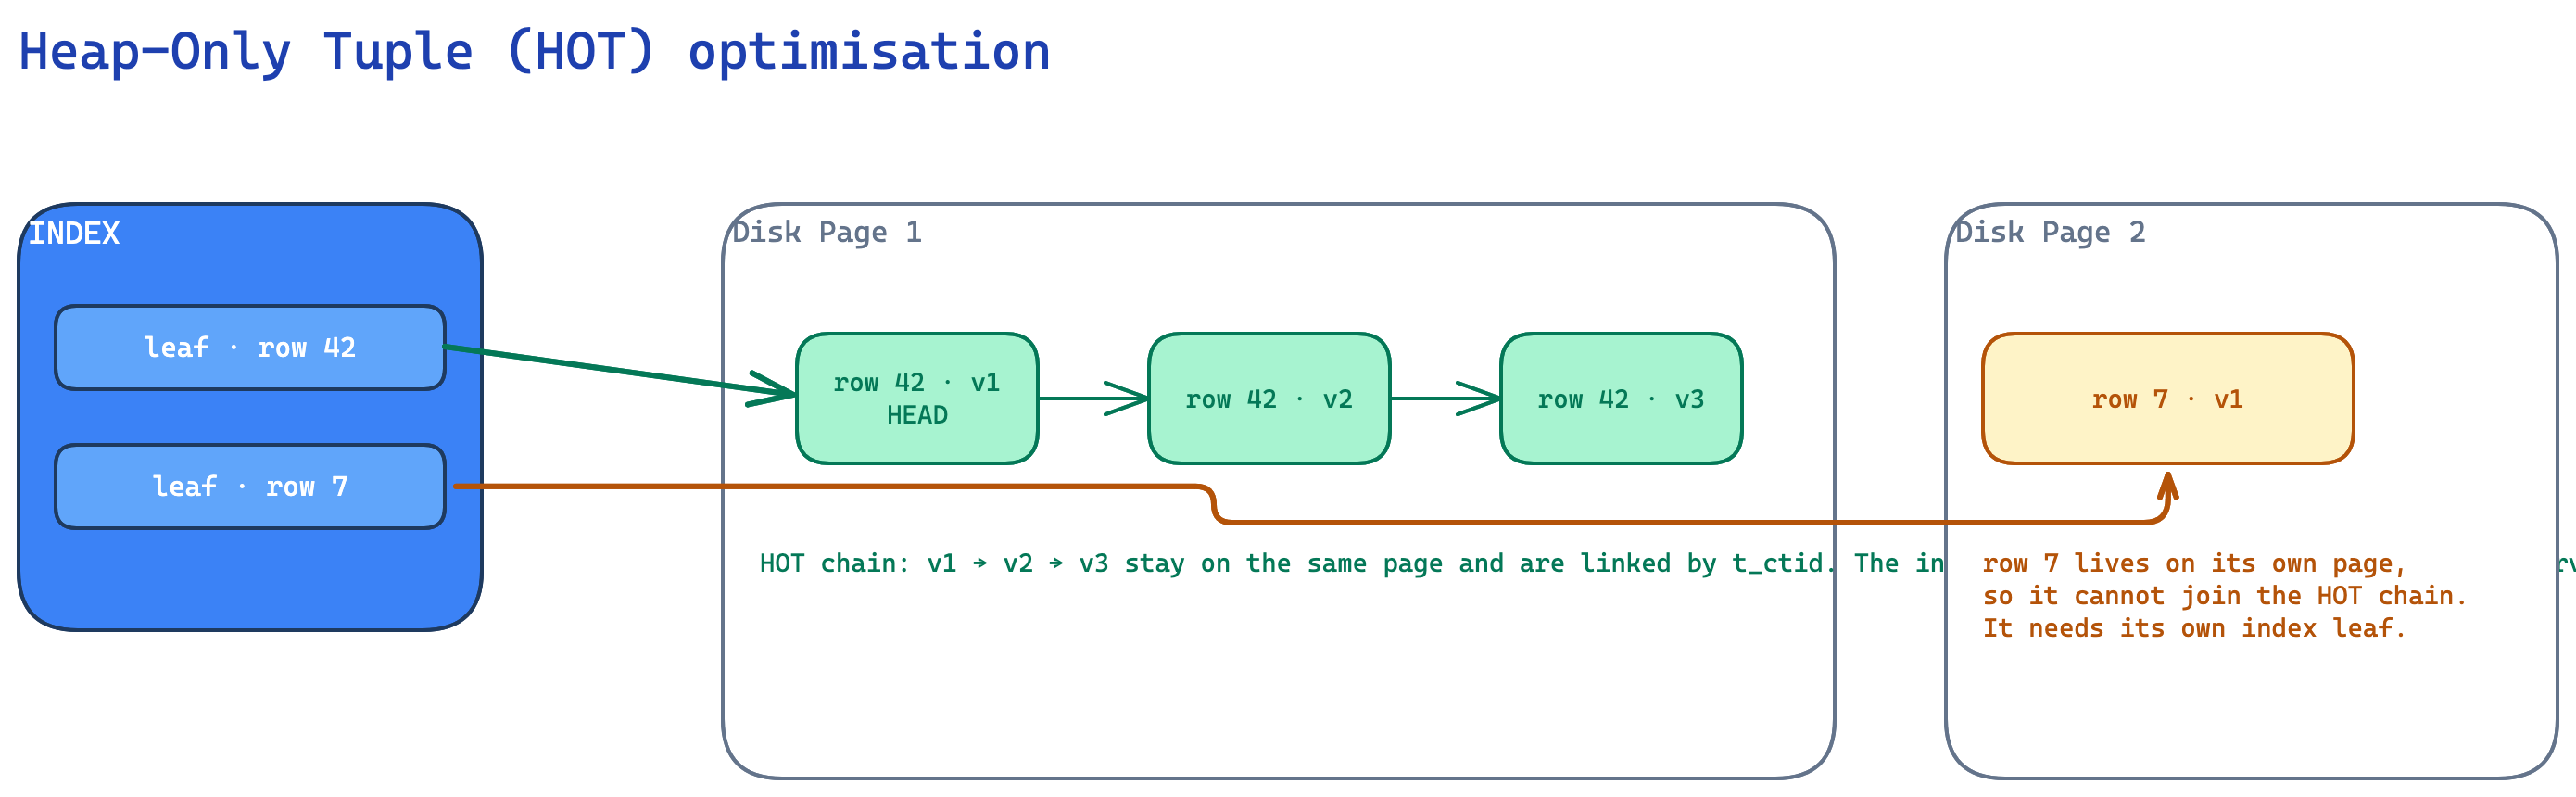
PostgreSQL tries to avoid adding multiple index entries and storing related versions over multiple pages by creating a new copy in the same disk page (block) as the old version to reduce disk I/O. This is called "heap-only tuple" optimisation.
PostgreSQL uses the HOT approach if an update does not modify any columns referenced by a table’s indexes and the new version is stored on the same disk page as the old version.
VACUUM - Pruning of stale versions
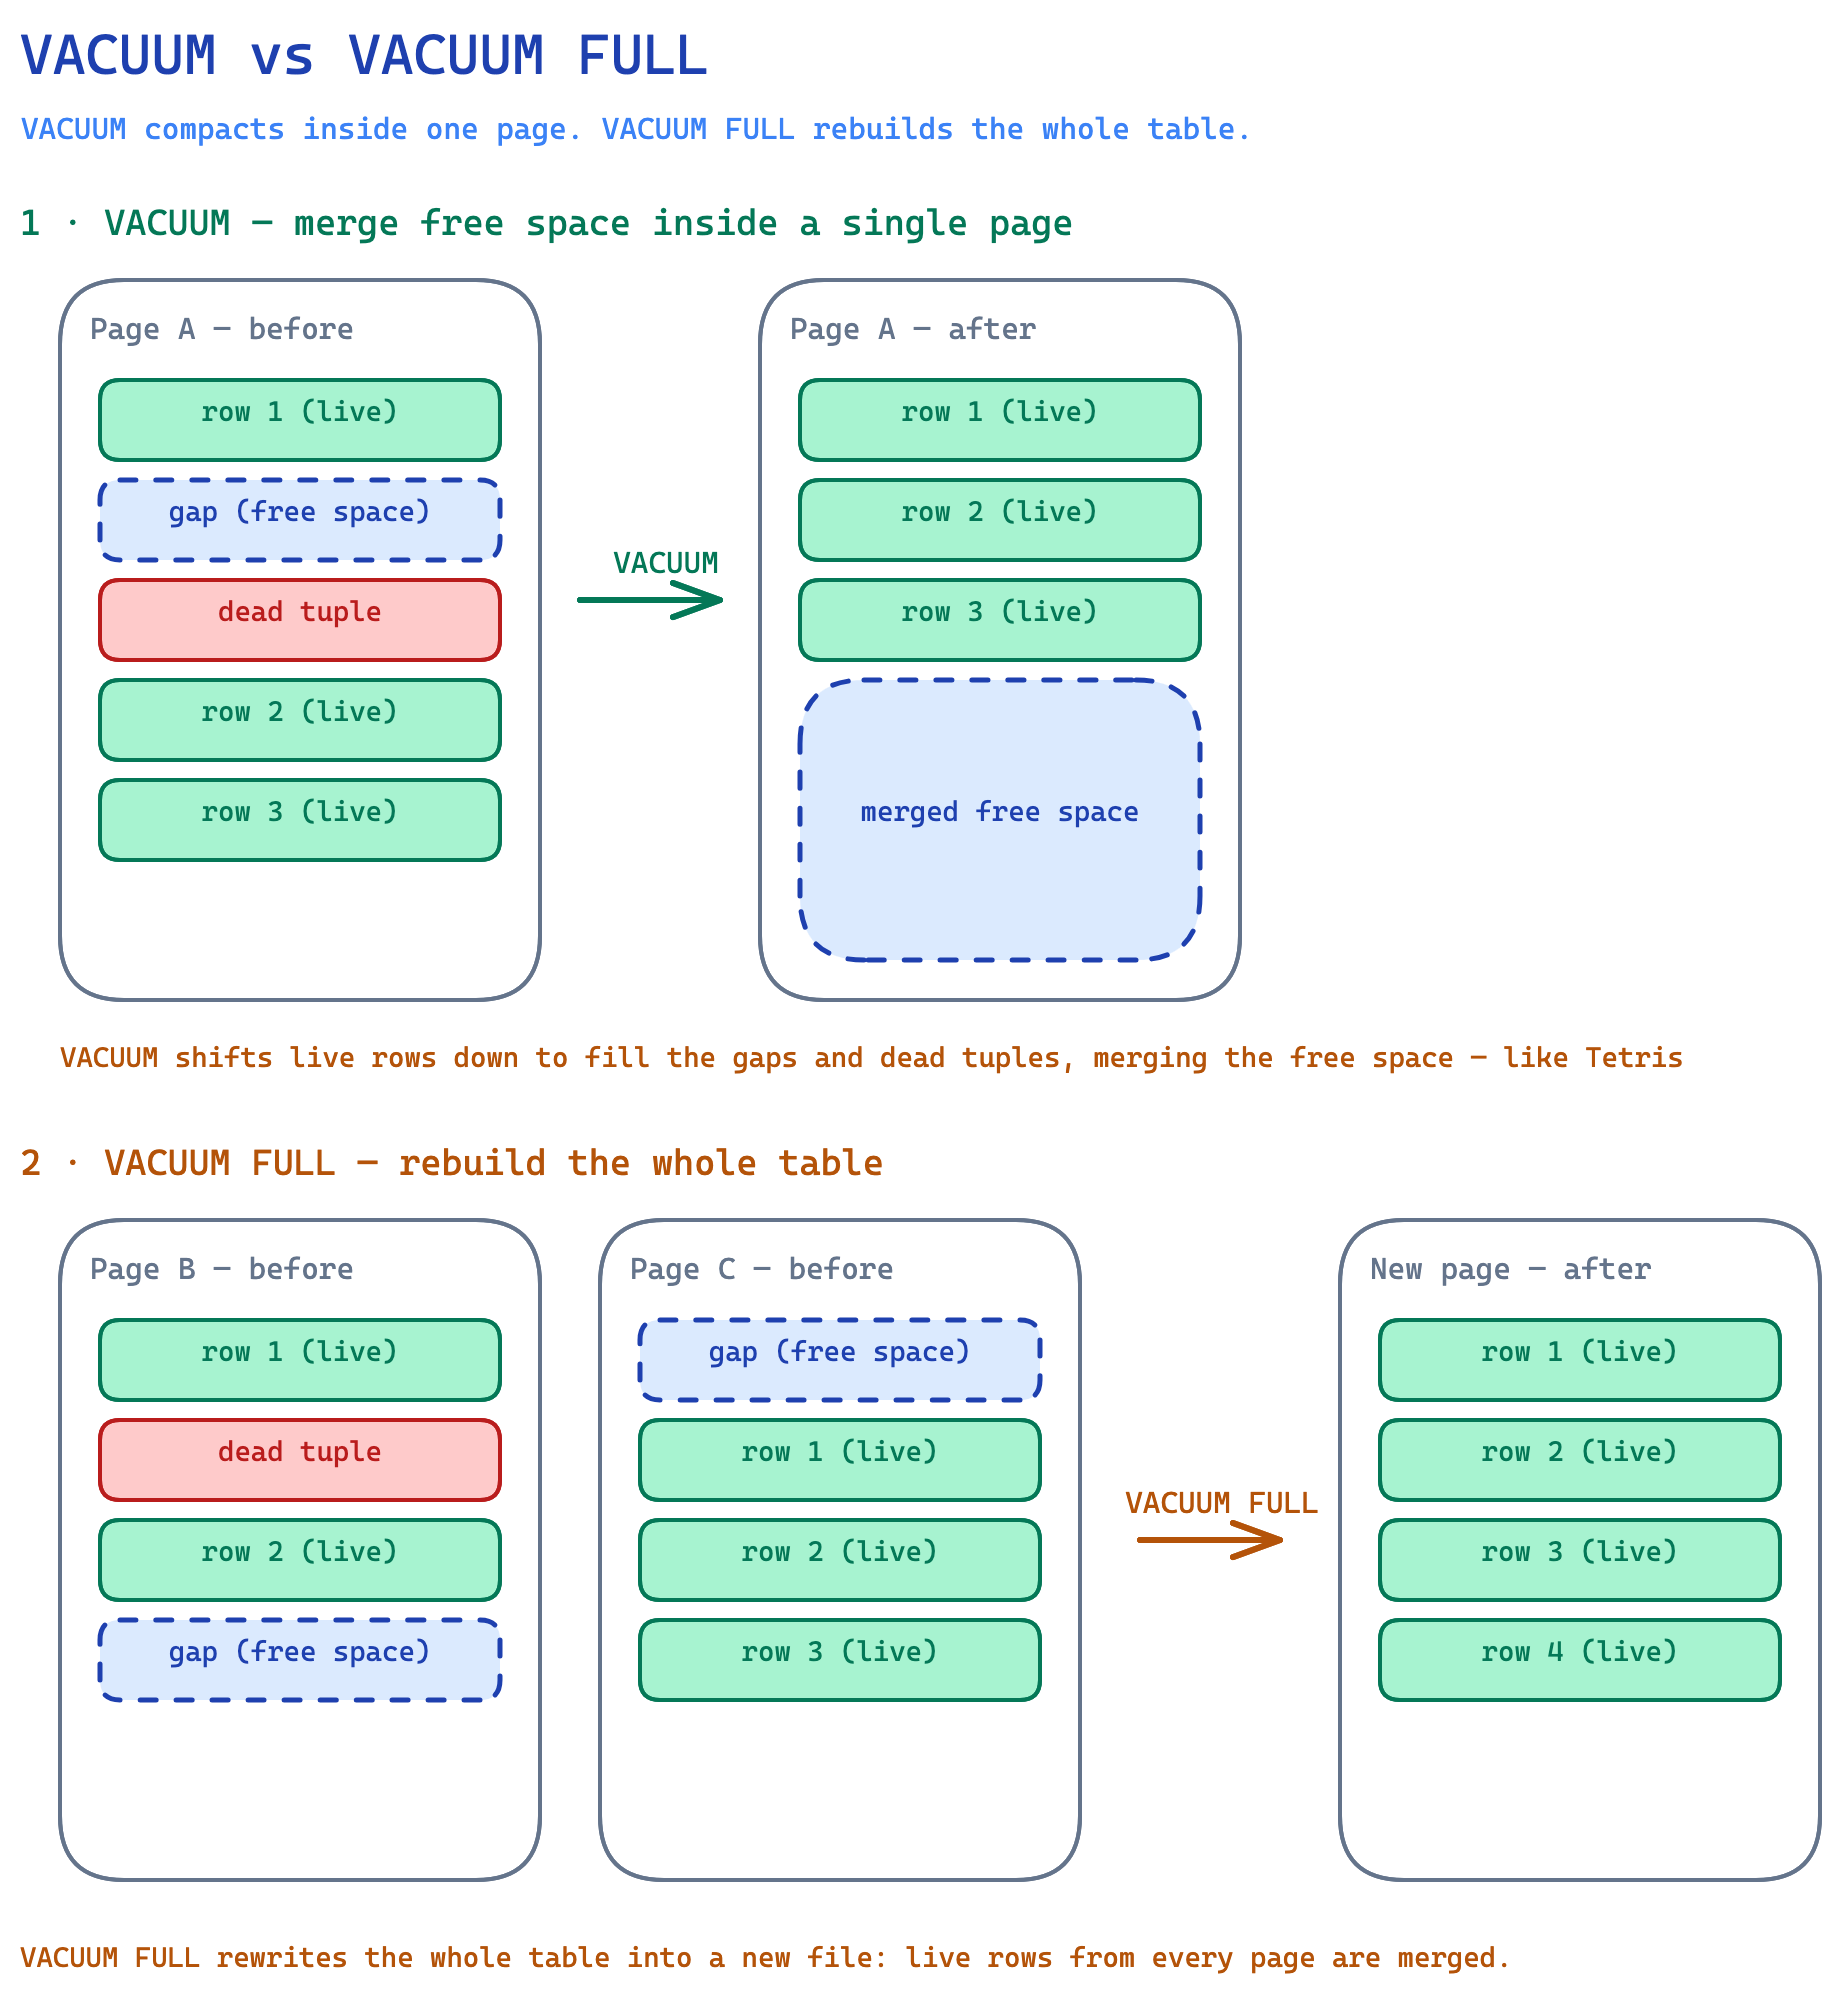
PostgreSQL uses a vacuum procedure that runs periodically to clean up dead tuples from tables. Although this helps but the write-heavy workloads can bloat up the table quickly.
It runs a sequential scan on the table disk pages modified since its last run and finds expired versions using the
t_xminandt_xmaxfields in the page header. A version is considered as expired if the row's transaction id is less than the current transaction id.Even though VACUUM procedure runs periodically and cleans up dead tuples, it cannot relocate and merge the live tuples across multiple pages. It only relocates within a single page. To reclaim and return unused space, we must use VACUUM FULL which rebuilds the entire table to a new space and it comes with performance implications. VACUUM FULL also takes an
ACCESS EXCLUSIVElock on the table, which blocks reads and writes for the whole rebuild, so it needs downtime on the table.
Case Study : Why Uber moved from PostgreSQL to MySQL
Write Amplification : Every update becomes much larger and costlier when translated to the physical layer. As mentioned above, On every row update, PostgreSQL creates a new version in the same tablespace, updates every index to point to newly created version.
Replication : DBMS maintains WAL (Write-Ahead Logging) to guarantee consistency and durability. They write each change (insert/update/delete) to an append-only file which will be used to recover the data in case of system crashes. When the updates happen in the master instance, instead of just the row and value updates, WAL pushes the index updates as well. This causes huge network bandwidth consumption when the replicas are not within the same datacenter.
Replica MVCC impacting active transactions : If a replica has an active transaction, MVCC updates (via WAL) to the rows held by the transaction are blocked until the transaction has ended.
Credits: Uber's blog post
MySQL
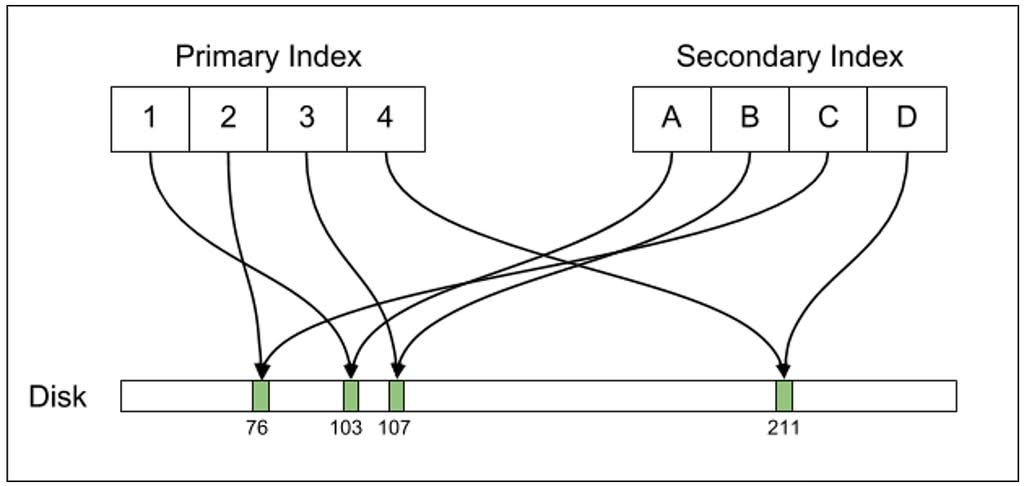
While Postgres directly maps index records to on-disk locations, InnoDB (MySQL Database Engine) maps to the primary key value.
For every index lookup, we need to make two lookups. One on secondary index, second on primary index to find the disk location. That's the disadvantage. The advantage is that the row updates needs to update only the primary index records.
MVCC and Index Handling
For MVCC, InnoDB copies the older rows to a special area called rollback segment (also called undo logs).
A secondary index does not store a physical address, and it does not store a version pointer. Each secondary index record stores the indexed columns plus a copy of the primary key columns. So the secondary index points to a primary key value, not to a row version.
A clustered index (primary key) record stores the full row plus two hidden columns.
DB_TRX_IDholds the transaction id that last changed the row.DB_ROLL_PTRis the pointer into the rollback segment. That undo record pointer holds the data needed to rebuild the older version. The older versions therefore form a chain inside the rollback segment, not inside the index.
secondary index record: (indexed columns, PK columns)
        │
        ▼  PK value
clustered index record: (full row, DB_TRX_ID, DB_ROLL_PTR)
        │
        ▼  DB_ROLL_PTR
undo log record  ──►  older undo log record  ──►  ...
InnoDB reads the row, compares
DB_TRX_IDagainst the reader's snapshot, and if the version is not visible, followsDB_ROLL_PTRinto the undo log. It rebuilds older versions this way until it finds one the snapshot can see.Let's take an example. One row exists:
account (id=1, balance=100). Three transactions change it:T10 inserts the row with
balance=100.T20 updates
balanceto 200.T30 updates
balanceto 300.
The current clustered index record is the newest version. It holds
balance=300,DB_TRX_ID=T30, andDB_ROLL_PTR=U30. This record is the head of the version chain (N2O).Each update writes an undo record. The undo record holds two different things:
The older values of the changed columns: the values that this update overwrote. T30 changed only
balance, so U30 storesbalance=200. InnoDB stores only the changed column-value pairs, not the whole row.The old values of two hidden columns: InnoDB adds
DB_TRX_IDandDB_ROLL_PTRto every row as hidden columns. They are not part of the table schema.DB_TRX_IDis the id of the transaction that last changed the row.DB_ROLL_PTRis the pointer to the undo record that holds the previous version. Before an update, InnoDB copies the old values of these two hidden columns into the undo record. For U30 these areDB_TRX_ID=T20andDB_ROLL_PTR=U20.
The example rows below show both parts together. Both parts live in the same undo record:
U30 holds
balance=200, oldDB_TRX_ID=T20, oldDB_ROLL_PTR=U20.U20 holds
balance=100, oldDB_TRX_ID=T10, oldDB_ROLL_PTR=U10.U10 is the insert undo of T10. It has no older version. The chain ends here.
What happens if an older transaction reads. Let's say
T25reads the current row:The clustered index lookup returns the head:
balance=300,DB_TRX_ID=T30,DB_ROLL_PTR=U30.Compare
T30with the snapshot.30 > 25, so a newer transaction changed the row. The current version is not visible.Fetch the undo record that
DB_ROLL_PTR=U30points to, that is U30. U30 holdsbalance=200, oldDB_TRX_ID=T20, and oldDB_ROLL_PTR=U20.Apply U30. This rebuilds the previous version as
balance=200, withDB_TRX_ID=T20andDB_ROLL_PTR=U20.Compare
T20with the snapshot.20 <= 25, so this version is visible. Returnbalance=200. The reader does not reach U20.
Similarly, snapshot T15 walks one version further:
30 > 15, so apply U30 to getbalance=200, trx=20.20 > 15, so apply U20 to getbalance=100, trx=10.10 <= 15, so returnbalance=100.Think of the chain is like a linked list made of stored pointers, not a page scan. Each version keeps its own
DB_ROLL_PTR. The current row points to the newest undo record. Each undo record stores the oldDB_ROLL_PTR, which points to the next older undo record. So the chain runs from newest to oldest through the rollback segment, and the head is always the row in the clustered index (N2O).

